
04 Capacity · GPU Capacity
Australian GPU capacity without owning the hardware.
Access Australian-hosted GPU infrastructure in the consumption model that fits your workload. Australian-hosted capacity planned against customer demand.
Model 01
On-Demand GPU capacity
Access GPUs for the duration of a job or project without a long-term commitment. Suited to experimentation, short training runs, development and burst requirements. Capacity is matched to project requirements and subject to availability.
Best for
- Experimentation
- Short training runs
- Burst workloads
- Development environments
Capacity is matched to project requirements and subject to availability.
Model 02
Reserved GPU capacity
Commit to capacity over an agreed term. For sustained workloads, reserved infrastructure can provide more predictable economics than purely consumption-based compute, and gives your team certainty that GPUs will be there when scheduled.
Best for
- Regular training
- Production workloads
- Research programmes
- Predictable capacity
Capacity is matched to project requirements and subject to availability.
Model 03
Dedicated GPU capacity
Single-tenant GPU servers allocated to your organisation for the term. Designed to support consistent utilisation, sensitive workloads and enterprise applications that benefit from isolation and predictable performance.
Best for
- Production AI
- Sensitive workloads
- Consistent utilisation
- Enterprise applications
Capacity is matched to project requirements and subject to availability.
Model 04
Private cluster GPU capacity
An isolated multi-node GPU environment with high-speed interconnect and its own platform layer, scoped to larger AI programmes, universities, government and regulated industries. Can be combined with the Managed AI Platform.
Best for
- Larger AI workloads
- Enterprise AI
- Universities
- Government and regulated industries
Capacity is matched to project requirements and subject to availability.
Compare
Which model fits?
| On-Demand | Reserved | Dedicated | Private Cluster | |
|---|---|---|---|---|
| Typical use case | Experimentation, burst, dev | Regular training, production | Production AI, sensitive workloads | Larger AI programmes, institutions |
| Commitment | None beyond usage | Agreed term | Agreed term | Agreed term |
| GPU isolation | Shared infrastructure | Allocated capacity | Single-tenant servers | Isolated multi-node environment |
| Capacity certainty | Subject to availability | Committed for the term | Committed for the term | Committed for the term |
| Scaling | Flexible, availability dependent | Planned with Peregrine | Add servers by agreement | Expand cluster by agreement |
| Pricing model | Per GPU-hour | Monthly term | Monthly term | Monthly term or project |
| Ideal customer | Teams exploring and iterating | Teams with steady workloads | Enterprises needing isolation | Universities, government, enterprise AI |
Hardware
Built around industry-leading GPU platforms.
GPU architecture and availability depend on deployment, capacity and project requirements.
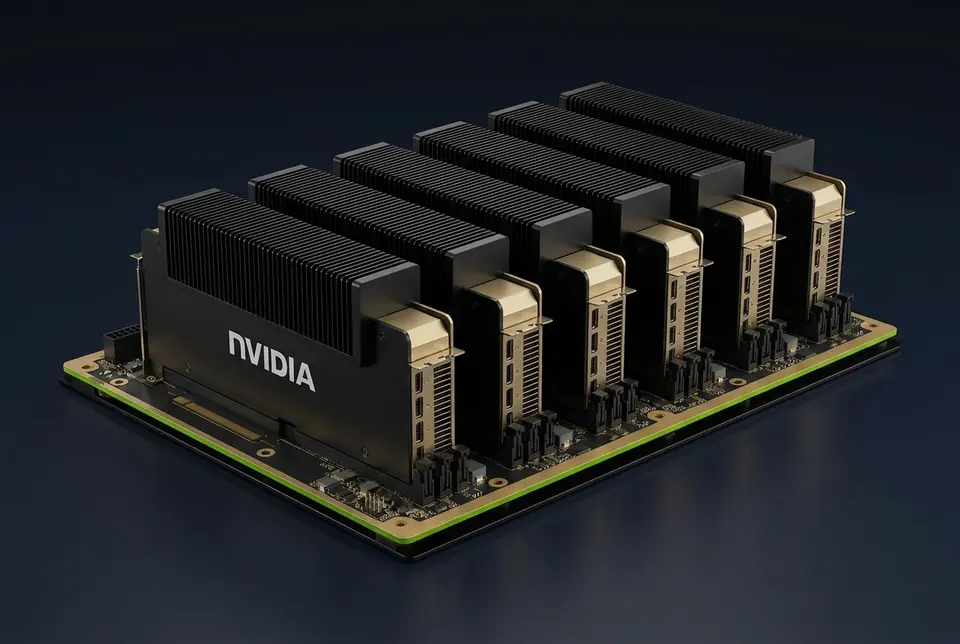
Blackwell Ultra
NVIDIA HGX B300
Large-scale training and high-throughput inference for reasoning models.
View platform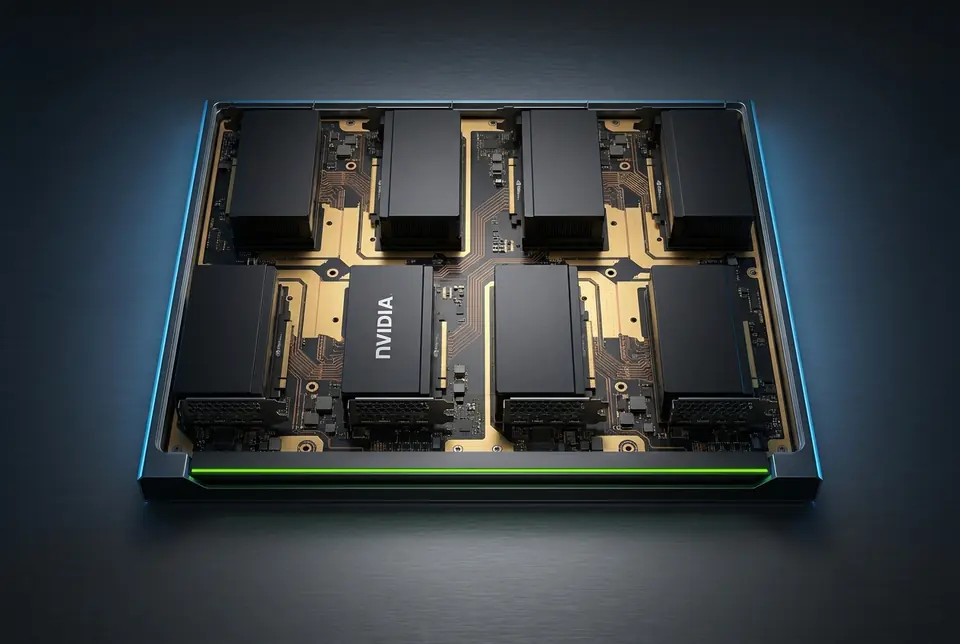
Blackwell
NVIDIA HGX B200
Balanced Blackwell platform for training and production inference.
View platform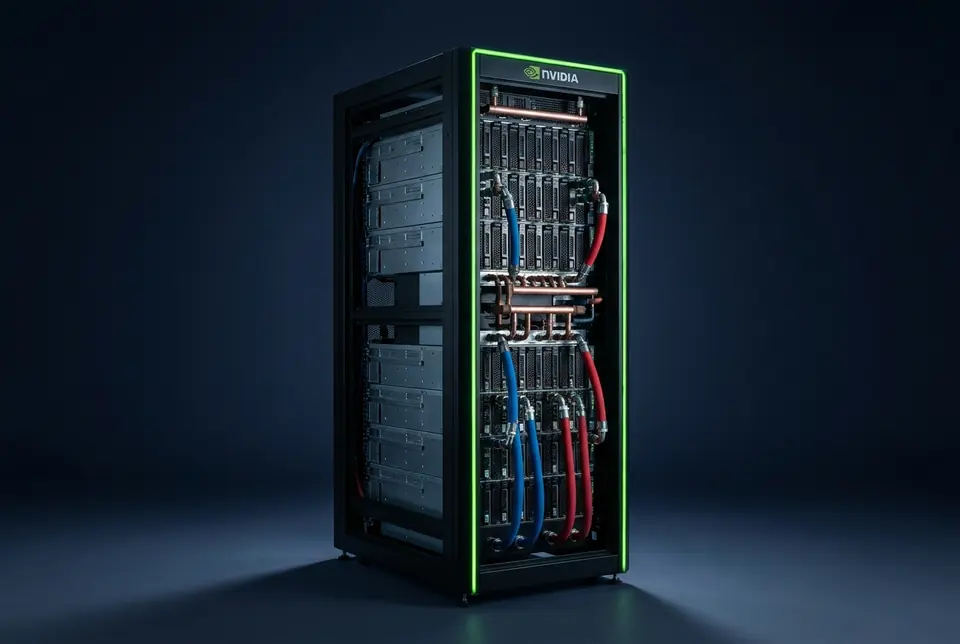
Rack-scale Blackwell
NVIDIA GB200 / GB300 NVL72-class
Rack-scale, liquid-cooled systems for very large tightly coupled clusters.
View platform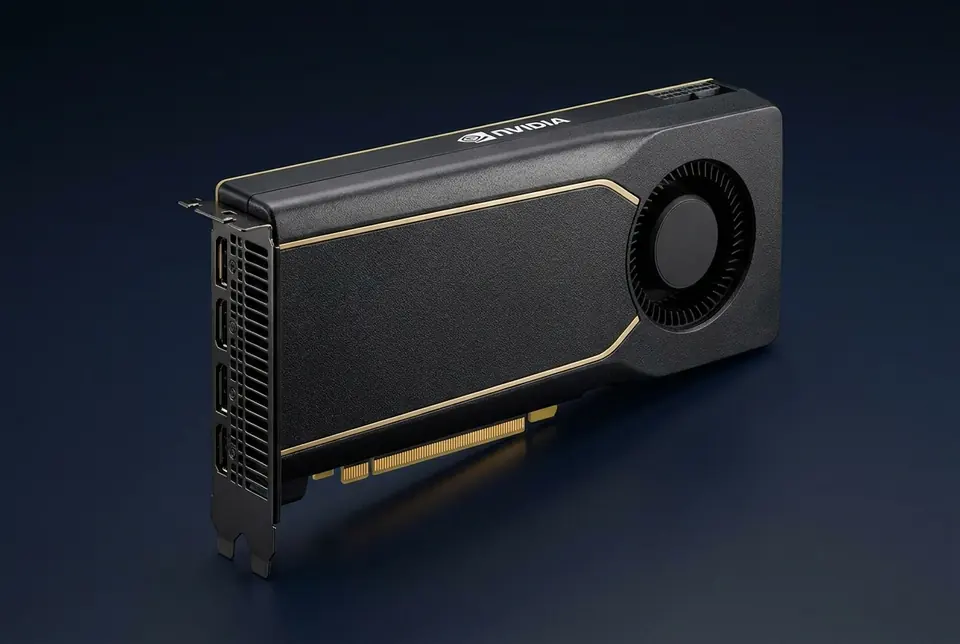
Blackwell · PCIe
NVIDIA RTX PRO 6000 Blackwell Server Edition
Cost-effective per-GPU memory for inference fleets, vision, rendering and digital twins.
View platform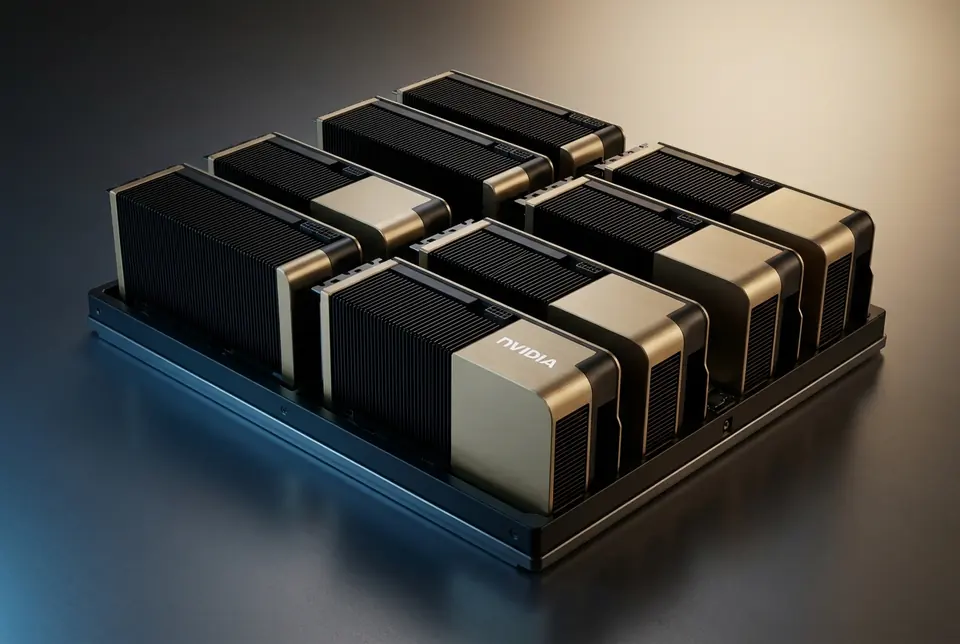
Hopper
NVIDIA HGX H200
Mature ecosystem with larger memory for inference of large models and training.
View platform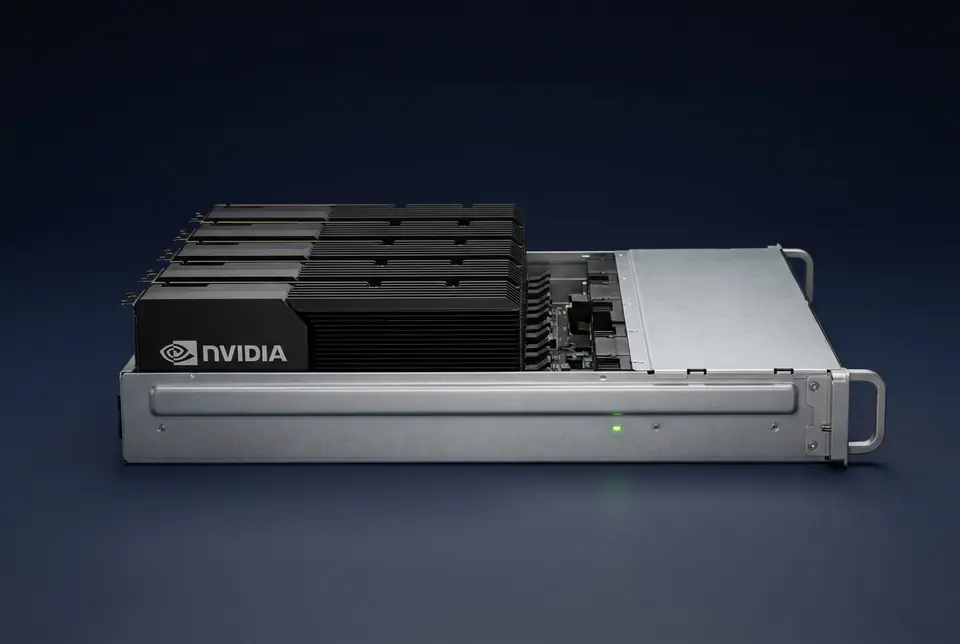
Hopper
NVIDIA HGX H100
Proven production platform with the broadest software maturity.
View platformWorkloads
Capacity for the work you actually run.
LLM Training
Multi-GPU and multi-node training for foundation and domain models.
LLM Fine-Tuning
Adapt open or proprietary models to your data.
Generative AI
Image, video, audio and text generation at production scale.
Production Inference
Serve models with predictable latency and capacity.
AI Agents
Run agentic systems with sustained inference demand.
Computer Vision
Train and serve detection, segmentation and classification models.
Robotics
Perception, policy learning and simulation for physical AI.
Scientific Computing
GPU-accelerated research and HPC-adjacent workloads.
Simulation
Engineering, physics and environmental simulation.
Digital Twins
Real-time models of physical assets and processes.
Rendering
GPU rendering for media, design and visualisation.
Data Analytics
Accelerated analytics and feature pipelines.
Australian-hosted capacity planned against customer demand.
Early capacity partners receive priority consideration when new capacity is commissioned.
Planning GPU capacity?
Register a non-binding forecast so capacity can be planned around your requirements, or talk to us about current availability.