Long cold aisle of server racks with active blue status LEDs

GPU Platforms

GPU platforms for training, inference and visualisation.

Peregrine designs, sources and commissions GPU systems for infrastructure you own, and deploys them within Peregrine capacity. Architecture and availability are subject to deployment and capacity availability.

NVIDIA Inception Program badge

Peregrine Compute is a member of the NVIDIA Inception Program.

Platforms

Six platforms, one accountable partner.

Systems are sourced through established OEM and distribution channels; vendor and configuration are selected per project.

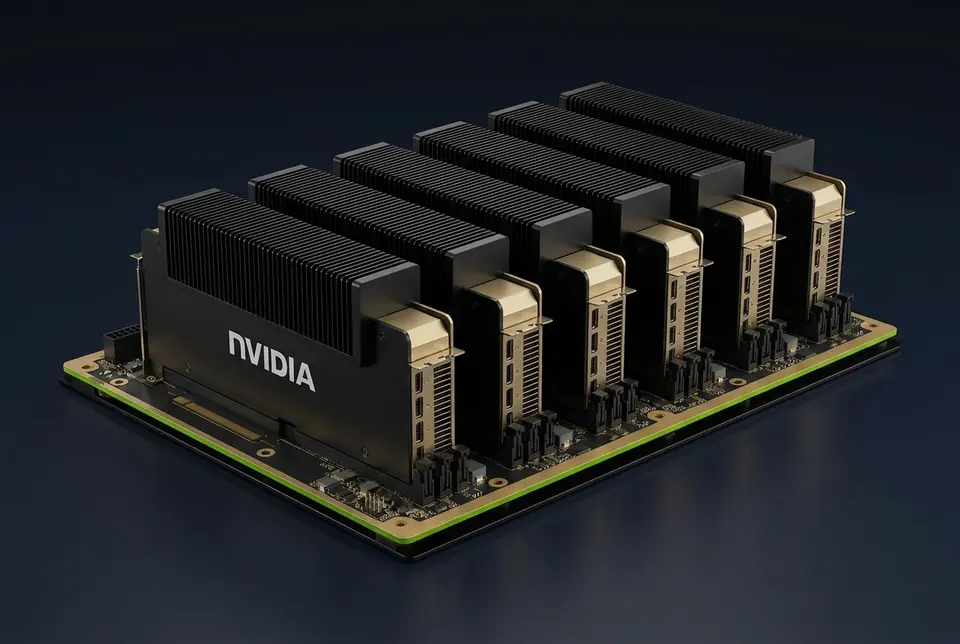
NVIDIA HGX B300 eight-GPU baseboard tray with NVIDIA-branded heatsink shrouds

Blackwell Ultra

NVIDIA HGX B300

Large-scale training and high-throughput inference for reasoning models.

Designed for

  • Large-scale LLM training
  • High-throughput inference
  • Reasoning and long-context models
  • Multi-node clusters

Best suited to

  • Frontier-scale training programmes
  • Inference fleets serving very large models
  • Organisations standardising on Blackwell Ultra
GPUs per system
8 (HGX baseboard)
Memory per GPU
Approx. 288 GB HBM3e (indicative)
Interconnect
NVLink all-to-all across 8 GPUs
Form factor
HGX 8-GPU server, air or liquid cooled

Indicative, based on NVIDIA published specifications. Final configuration determined per project.
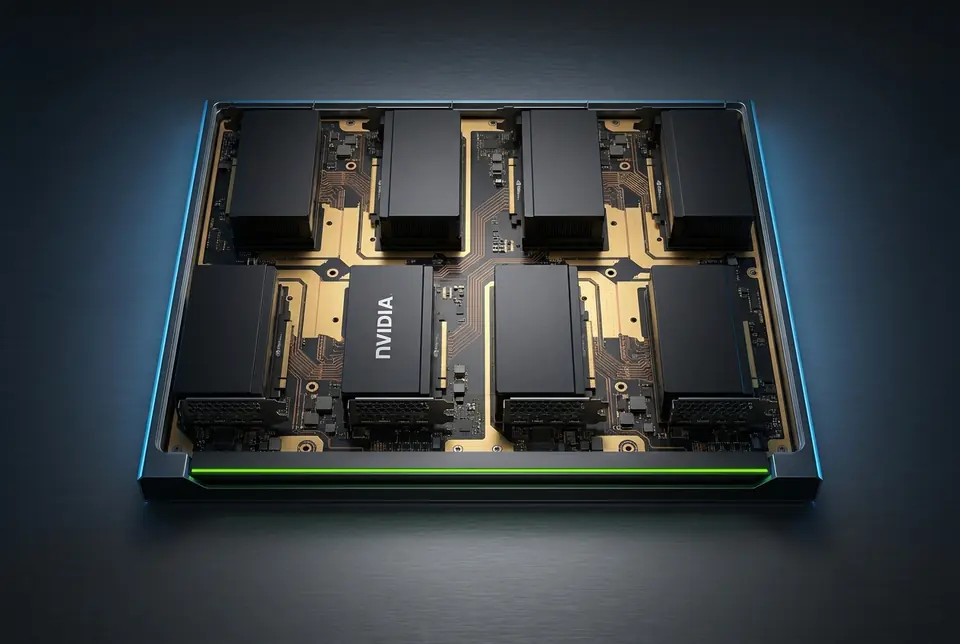
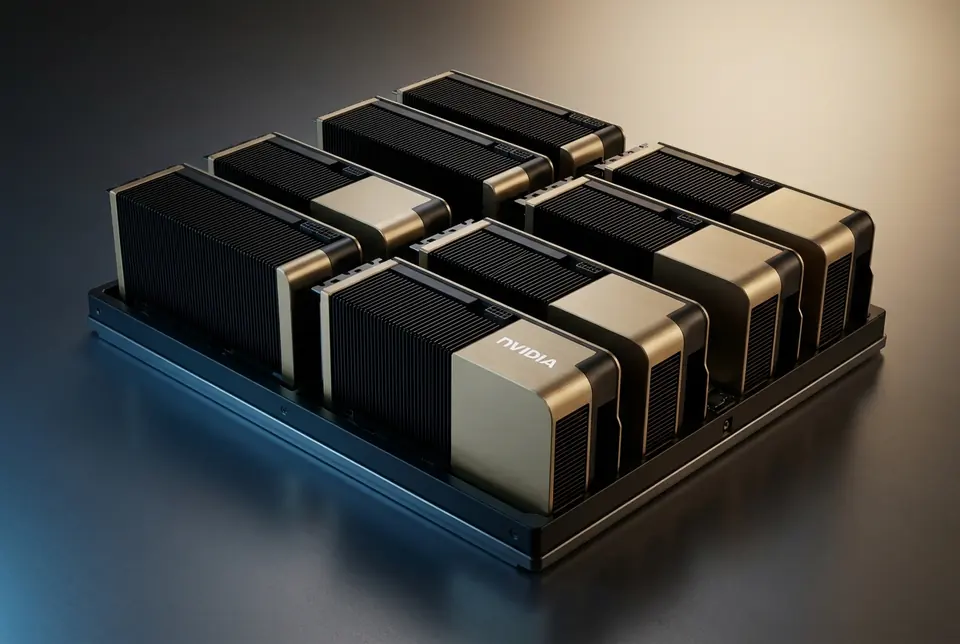
Top-down view of an NVIDIA HGX B200 eight-GPU baseboard

Blackwell

NVIDIA HGX B200

Balanced Blackwell platform for training and production inference.

Designed for

  • LLM training and fine-tuning
  • Production inference
  • Generative AI
  • Mixed training / inference clusters

Best suited to

  • Enterprises and AI companies building production clusters
  • Research groups training large models
  • Reserved or dedicated capacity
GPUs per system
8 (HGX baseboard)
Memory per GPU
Approx. 180 GB HBM3e (indicative)
Interconnect
NVLink all-to-all across 8 GPUs
Form factor
HGX 8-GPU server, air or liquid cooled

Indicative, based on NVIDIA published specifications. Final configuration determined per project.
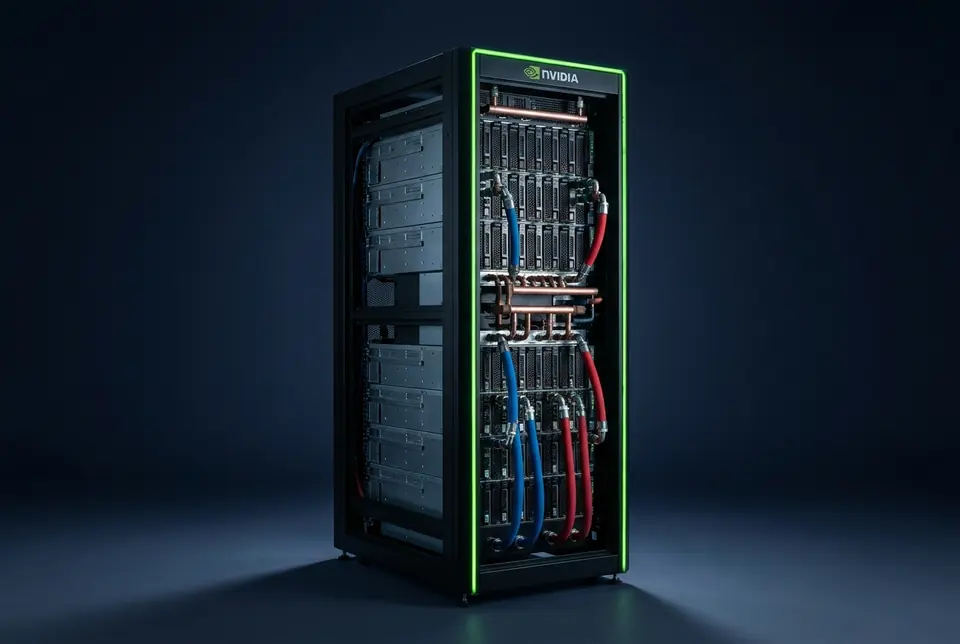
NVIDIA GB200-class liquid-cooled rack-scale system with coolant manifolds

Rack-scale Blackwell

NVIDIA GB200 / GB300 NVL72-class

Rack-scale, liquid-cooled systems for very large tightly coupled clusters.

Designed for

  • Very large tightly coupled training
  • Trillion-parameter-class inference
  • Rack-scale NVLink domains

Best suited to

  • Project-specific, deployment dependent
  • Facilities with liquid-cooling and high power density
  • Programmes requiring rack-scale NVLink
Architecture
Grace CPU + Blackwell GPUs
NVLink domain
Up to 72 GPUs per rack (indicative)
Cooling
Direct liquid cooling
Form factor
Integrated rack-scale system

Indicative, based on NVIDIA published specifications. Final configuration determined per project.
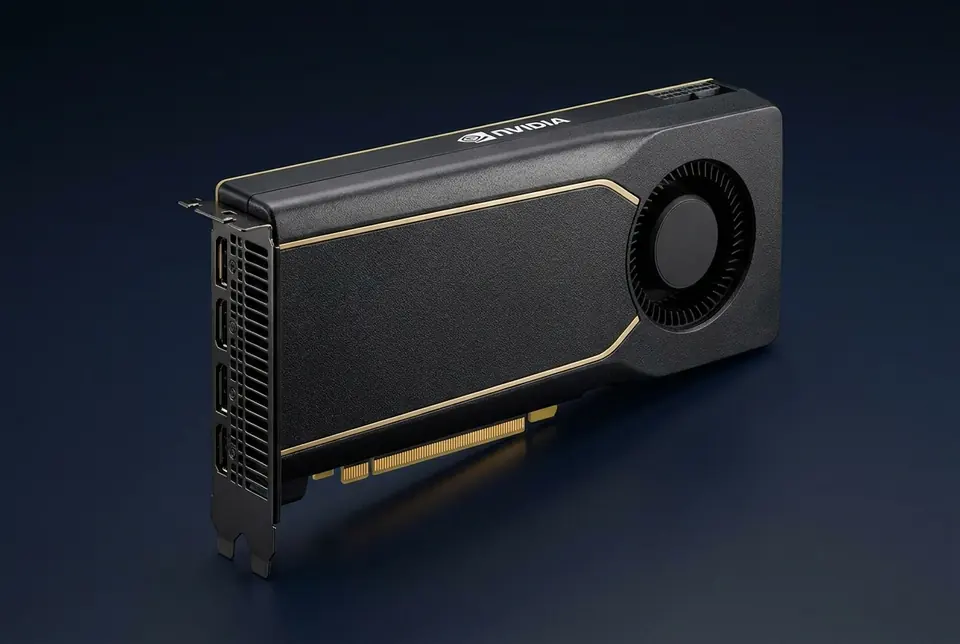
NVIDIA RTX PRO 6000 Blackwell Server Edition dual-slot PCIe card

Blackwell · PCIe

NVIDIA RTX PRO 6000 Blackwell Server Edition

Cost-effective per-GPU memory for inference fleets, vision, rendering and digital twins.

Designed for

  • Inference and fine-tuning
  • Computer vision
  • Rendering and visualisation
  • Digital twins and simulation

Best suited to

  • Inference fleets where memory per dollar matters
  • Vision, rendering and visualisation workloads
  • Teams that do not need NVLink coupling
Interface
PCIe Gen5, dual-slot
Memory per GPU
Approx. 96 GB GDDR7 (indicative)
GPUs per server
Typically 4–8
Form factor
2U–4U PCIe servers

Indicative, based on NVIDIA published specifications. Final configuration determined per project.
NVIDIA HGX H200 eight-GPU tray with gold-and-black heatsinks

Hopper

NVIDIA HGX H200

Mature ecosystem with larger memory for inference of large models and training.

Designed for

  • Inference of large models
  • LLM training and fine-tuning
  • Memory-bound workloads

Best suited to

  • Production inference of 70B+ class models
  • Teams with established Hopper tooling
  • Reserved capacity
GPUs per system
8 (HGX baseboard)
Memory per GPU
Approx. 141 GB HBM3e (indicative)
Interconnect
NVLink across 8 GPUs
Form factor
HGX 8-GPU server, air cooled

Indicative, based on NVIDIA published specifications. Final configuration determined per project.
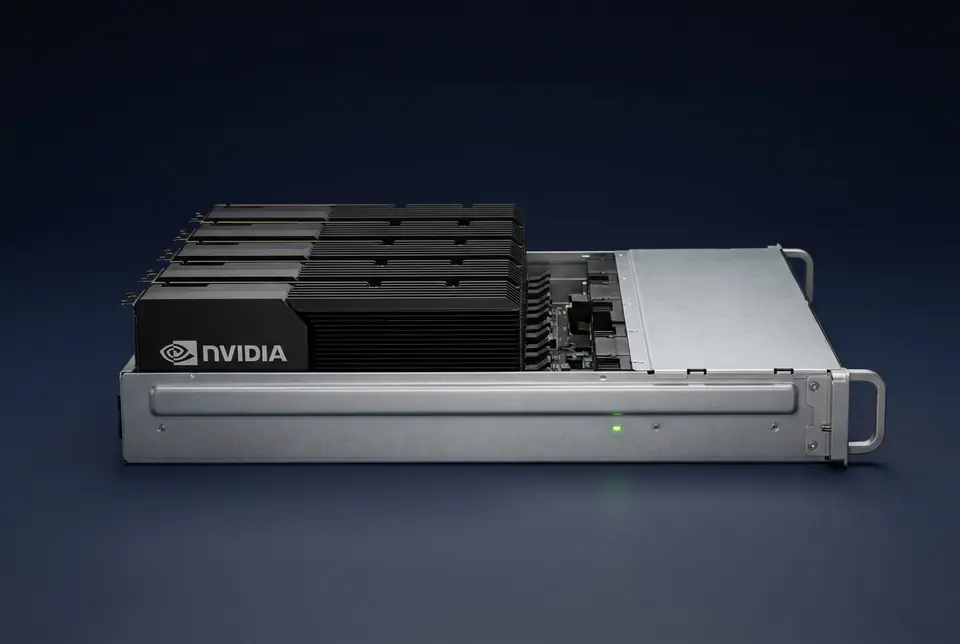
NVIDIA HGX H100 eight-GPU tray in a server sled

Hopper

NVIDIA HGX H100

Proven production platform with the broadest software maturity.

Designed for

  • Training and fine-tuning
  • Production inference
  • Research clusters

Best suited to

  • Universities and research institutes
  • Established production workloads
  • On-demand and reserved capacity
GPUs per system
8 (HGX baseboard)
Memory per GPU
Approx. 80 GB HBM3 (indicative)
Interconnect
NVLink across 8 GPUs
Form factor
HGX 8-GPU server, air cooled

Indicative, based on NVIDIA published specifications. Final configuration determined per project.
Choosing a platform

Compare at a glance.

Indicative, based on NVIDIA published specifications. Final configuration determined per project.

 B300B200NVL72-classRTX PRO 6000H200H100
Memory per GPU (indicative)~288 GB HBM3e~180 GB HBM3eBlackwell GPUs, rack-scale~96 GB GDDR7~141 GB HBM3e~80 GB HBM3
InterconnectNVLink HGXNVLink HGXNVLink rack-scalePCIe + optional bridgeNVLink HGXNVLink HGX
Form factor8-GPU HGX server8-GPU HGX serverLiquid-cooled rack2U–4U PCIe server8-GPU HGX server8-GPU HGX server
Primary workloadsTraining, reasoning inferenceTraining, inferenceVery large coupled clustersInference, CV, rendering, twinsLarge-model inference, trainingTraining, inference
Typical cluster scaleMulti-nodeSingle to multi-nodeRack to multi-rackSingle node to fleetsSingle to multi-nodeSingle to multi-node
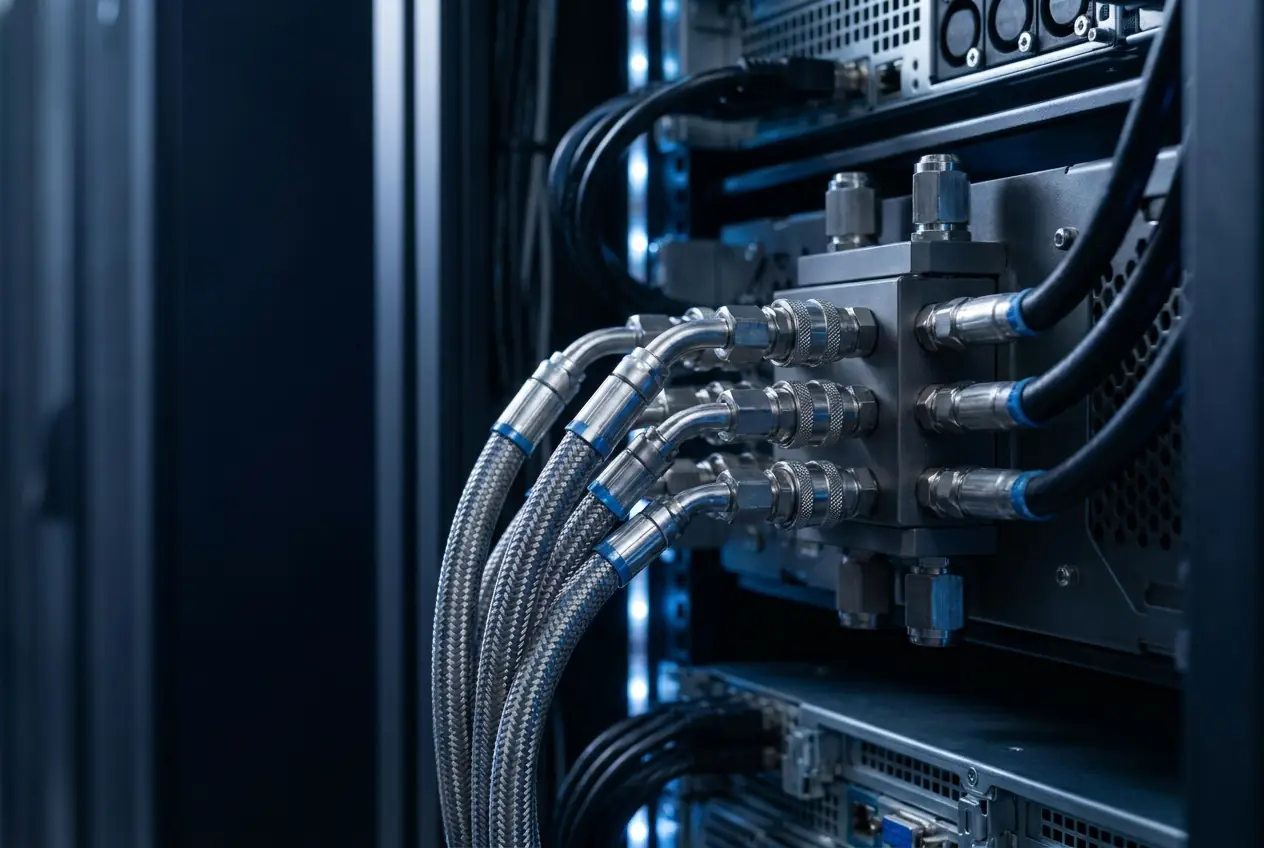
Liquid coolant lines and manifold on the rear of a GPU rack

HGX vs PCIe

HGX vs PCIe: when NVLink coupling matters — and when it doesn't.

HGX (NVLink-coupled) platforms connect eight GPUs with high-bandwidth NVLink so they behave like one large accelerator. This matters for large-model training, tensor and pipeline parallelism, and inference of models that do not fit in a single GPU's memory.

PCIe platforms such as RTX PRO 6000 Blackwell suit workloads that scale across independent GPUs: inference fleets serving many model replicas, computer vision pipelines, rendering, digital twins and fine-tuning of models that fit in one GPU. They typically offer more memory per dollar and flexible server form factors.

Most organisations end up with a mix. The Compute Blueprint maps your workloads to the right platform for each.

Not sure which platform?

Let a Compute Blueprint decide.

A fixed-fee assessment sizes your workloads and recommends the platform, interconnect and cluster scale — before you commit. Typical engagement: approximately 2 weeks.

Request a Compute Blueprint

Build with a platform, or request capacity.

Tell us which platform and workload you have in mind. We will confirm fit, deployment options and availability.